• About Us
  • Disclaimer
  • Contact Us
  • Privacy Policy
Wednesday, September 16, 2026
mGrowTech
No Result
View All Result
  • Technology And Software
    • Account Based Marketing
    • Channel Marketing
    • Marketing Automation
      • Al, Analytics and Automation
      • Ad Management
  • Digital Marketing
    • Social Media Management
    • Google Marketing
  • Direct Marketing
    • Brand Management
    • Marketing Attribution and Consulting
  • Mobile Marketing
  • Event Management
  • PR Solutions
  • Technology And Software
    • Account Based Marketing
    • Channel Marketing
    • Marketing Automation
      • Al, Analytics and Automation
      • Ad Management
  • Digital Marketing
    • Social Media Management
    • Google Marketing
  • Direct Marketing
    • Brand Management
    • Marketing Attribution and Consulting
  • Mobile Marketing
  • Event Management
  • PR Solutions
No Result
View All Result
mGrowTech
No Result
View All Result
Home Al, Analytics and Automation

Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture

Josh by Josh
August 26, 2026
in Al, Analytics and Automation
0
Alibaba’s Qwen Team Releases Qwen3.8-Flash-Next: A 125B Multimodal MoE With 6B Active Parameters Previewing the Qwen4 Architecture

[ad_1]

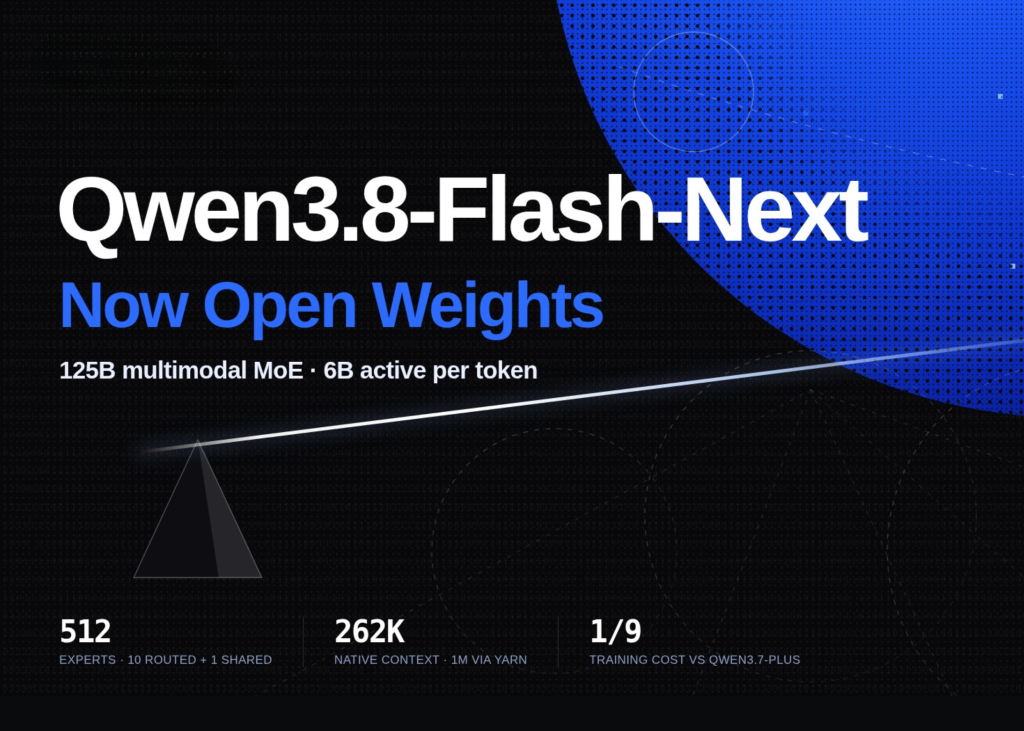
Alibaba’s Qwen team has released Qwen3.8-Flash-Next, an open-weight multimodal Mixture-of-Experts model built for cost per token. The checkpoint pairs a 125B backbone with a 51B N-gram embedding table and a 4B multi-token prediction module. Only 6B parameters activate per token. The team positions it as an early preview of the architecture that will underpin Qwen4, the same role Qwen3-Next played for Qwen3.5. Four changes carry the release: a Gated DeltaNet and Qwen Sparse Attention hybrid, Gated Residual, N-gram Embedding, and the Muon optimizer. Qwen team reports training cost at roughly one-ninth that of Qwen3.7-Plus.

Is it deployable?

Yes but not on a workstation. The FP8 checkpoint is 172.78 GiB and the BF16 checkpoint is 335.28 GiB. Per vLLM recipes, TP2 is the minimum validated FP8 configuration on GB300 and TP4 is recommended. On an 8×H200 node, use TEP8; plain TP8 is incompatible with the checkpoint’s 128-wide quantization blocks. Sparse activation cuts compute, not storage.

READ ALSO

XPENG Commissions Humanoid Robot Lines as IRON Walks Off Production – Unite.AI

Matt Clifford Steps Down as ARIA Chair After Anthropic Move – Unite.AI

What is actually new

Qwen3.8-Flash-Next pairs a 125B main model with 51B N-gram embedding parameters and a 4B multi-token prediction module, totaling 180B on disk. Only 6B parameters activate per token. Four changes drive this:

  • Hybrid attention (GDN + QSA): Three of every four layers use Gated DeltaNet, a linear-attention layer that compresses history into a fixed-size recurrent state. The fourth layer runs Qwen Sparse Attention (QSA), which uses a lightweight indexer to select context at micro-block granularity rather than per token. The layer layout is 12 × (3 × GDN → 1 × QSA) across 48 layers, with a QSA budget of 512 blocks or 2048 tokens.
  • Gated Residual: The residual stream widens into 4 parallel branches, with an element-wise read gate and a per-branch scalar write gate, at bottleneck rank 320.
  • N-gram Embedding: A 20,000,000-entry bigram/trigram table at layer 2 adds capacity through deterministic lookups. It can be offloaded to host memory with asynchronous prefetch — though offload currently runs only on NVIDIA devices.
  • Training recipe.:The Muon optimizer is applied alongside AdamW to specific weight categories, with batch-size warmup eliminated and scaling laws refitted.

The MoE layer carries 512 experts, activating 10 routed plus 1 shared, at expert intermediate dimension 640.

Benchmarks

Qwen reports 58.7 on DeepSWE 1.1, 62.5 on SWE-bench Pro, 81.0 on SWE-bench Multilingual, and 91.9 on LiveCodeBench v6. On agentic tasks it posts 73.9 on CoWorkBench, 55.7 on JobBench, and 73.5 on Toolathlon Verified. Multimodal results include 84.5 on AndroidWorld, 76.6 on LVBench, 88.5 on RealWorldQA, and 95.7 on MathVision with code interpreter.

The model does not lead everywhere. Claude Opus 4.6 (Max) takes HLE at 40.0 against Qwen’s 35.9, and DeepSeek-V4-Flash-0731 leads NL2Repo-Bench at 54.2 versus 48.1. Frontier reasoning remains the gap.

Efficiency

Qwen states training cost roughly 1/9 that of Qwen3.7-Plus. On serving, the announcement cites QSA kernel speedups of up to 7.6× prefill and 4.9× decode at 1M tokens, while the SGLang cookbook and vLLM recipes cite 10.2× and 6.6×. Treat the range as vendor-reported until independently measured. Qwen also reports 8.6× the prefill throughput of Qwen3.7-Plus at a 90% prefix-cache hit rate.

Context is 262,144 tokens natively, extensible to 1,000,000 with YaRN.

Running it

The model serves through vLLM, SGLang, TokenSpeed, transformers serve, and llama.cpp for GGUF quants. Fine-tuning is supported via Unsloth, Swift, and LLaMA-Factory. It already powers the “Standard” mode on QwenWork and works with Qwen Code.

Thinking mode is on by default, with reasoning_effort at xhigh, medium, or low. Qwen recommends temperature 1.0 and top_p 0.95 for thinking mode, and temperature 0.7 with top_p 0.80 for instruct mode.

Key Takeaways

  • 125B backbone + 51B N-gram embeddings + 4B MTP, with only 6B parameters active per token.
  • Three of four layers use Gated DeltaNet; the fourth runs Qwen Sparse Attention at micro-block granularity.
  • Trained at roughly 1/9 the cost of Qwen3.7-Plus, with 262K native context extensible to 1M via YaRN.
  • FP8 weights are 172.78 GiB, so self-hosting needs a multi-GPU node, not a workstation.
  • Licensed under qwen-community-1.0, not Apache-2.0 — verify terms before commercial use.

Check out the GitHub Page, HF Model Card and Technical Details. Also, feel free to follow us on Twitter and don’t forget to join our 150k+ML SubReddit and Subscribe to our Newsletter. Wait! are you on telegram? now you can join us on telegram as well.


Asif Razzaq is the CEO of Marktechpost Media Inc.. As a visionary entrepreneur and engineer, Asif is committed to harnessing the potential of Artificial Intelligence for social good. His most recent endeavor is the launch of an Artificial Intelligence Media Platform, Marktechpost, which stands out for its in-depth coverage of machine learning and deep learning news that is both technically sound and easily understandable by a wide audience. The platform boasts of over 2 million monthly views, illustrating its popularity among audiences.

[ad_2]

Source_link
Related Posts

XPENG Commissions Humanoid Robot Lines as IRON Walks Off Production – Unite.AI
Al, Analytics and Automation

XPENG Commissions Humanoid Robot Lines as IRON Walks Off Production – Unite.AI

September 8, 2026
Matt Clifford Steps Down as ARIA Chair After Anthropic Move – Unite.AI
Al, Analytics and Automation

Matt Clifford Steps Down as ARIA Chair After Anthropic Move – Unite.AI

September 7, 2026
In “An Alien Mind,” OpenAI’s Jakub Pachocki Urges Shared Safety Bars – Unite.AI
Al, Analytics and Automation

In “An Alien Mind,” OpenAI’s Jakub Pachocki Urges Shared Safety Bars – Unite.AI

September 7, 2026
H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder
Al, Analytics and Automation

H Company Releases NeoMME: A Family of 260M and 800M Single-Tower Multimodal Encoders That Drop the Vision Tower and Causal Decoder

September 7, 2026
The Model, Tools, Memory, and Control Loop – Unite.AI
Al, Analytics and Automation

The Model, Tools, Memory, and Control Loop – Unite.AI

September 6, 2026
UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data, Evaluation and RL for Computer-Use Agents
Al, Analytics and Automation

UC Berkeley Researchers Release CUA-Lite, an Open Platform Unifying Sandboxes, Data, Evaluation and RL for Computer-Use Agents

September 6, 2026
Next Post
ASUS Introduces New Ace Esports-Focused Gaming Monitors

ASUS Introduces New Ace Esports-Focused Gaming Monitors

POPULAR NEWS

Trump ends trade talks with Canada over a digital services tax

Trump ends trade talks with Canada over a digital services tax

June 28, 2025
15 Trending Songs on TikTok in 2025 (+ How to Use Them)

15 Trending Songs on TikTok in 2025 (+ How to Use Them)

June 18, 2025
Communication Effectiveness Skills For Business Leaders

Communication Effectiveness Skills For Business Leaders

June 10, 2025
Comparing the Top 7 Large Language Models LLMs/Systems for Coding in 2025

Comparing the Top 7 Large Language Models LLMs/Systems for Coding in 2025

November 4, 2025
App Development Cost in Singapore: Pricing Breakdown & Insights

App Development Cost in Singapore: Pricing Breakdown & Insights

June 22, 2025

EDITOR'S PICK

3 media relations myths

July 13, 2025
School of Architecture and Planning welcomes new faculty for 2025 | MIT News

School of Architecture and Planning welcomes new faculty for 2025 | MIT News

August 7, 2025
Top 10 Computer Vision Data Labeling Companies 2026

Top 10 Computer Vision Data Labeling Companies 2026

November 7, 2025
9 OneSignal alternatives for push notifications, email, SMS & more

9 OneSignal alternatives for push notifications, email, SMS & more

June 6, 2025

About

We bring you the best Premium WordPress Themes that perfect for news, magazine, personal blog, etc. Check our landing page for details.

Follow us

Categories

  • Account Based Marketing
  • Ad Management
  • Al, Analytics and Automation
  • Brand Management
  • Channel Marketing
  • Digital Marketing
  • Direct Marketing
  • Event Management
  • Google Marketing
  • Marketing Attribution and Consulting
  • Marketing Automation
  • Mobile Marketing
  • PR Solutions
  • Social Media Management
  • Technology And Software
  • Uncategorized

Recent Posts

  • The AI visibility gap: Why great brands disappear from AI answers
  • XPENG Commissions Humanoid Robot Lines as IRON Walks Off Production – Unite.AI
  • Google partners on West Virginia energy storage project
  • Gemini Live and Find Hub
  • About Us
  • Disclaimer
  • Contact Us
  • Privacy Policy
No Result
View All Result
  • Technology And Software
    • Account Based Marketing
    • Channel Marketing
    • Marketing Automation
      • Al, Analytics and Automation
      • Ad Management
  • Digital Marketing
    • Social Media Management
    • Google Marketing
  • Direct Marketing
    • Brand Management
    • Marketing Attribution and Consulting
  • Mobile Marketing
  • Event Management
  • PR Solutions