[ad_1]
What is an Embedding Model and What is it Used For?
In modern AI architectures, embedding models serve as the foundational translators bridging raw unstructured data and downstream intelligent reasoning. Simply put, embedding models translate inputs of various types of data — including text, images, and audio — into dense vector math. These high-dimensional numeric arrays capture semantic relationships, powering critical enterprise capabilities such as semantic search, recommender systems, intent classification, personalized content discovery, and vector clustering.
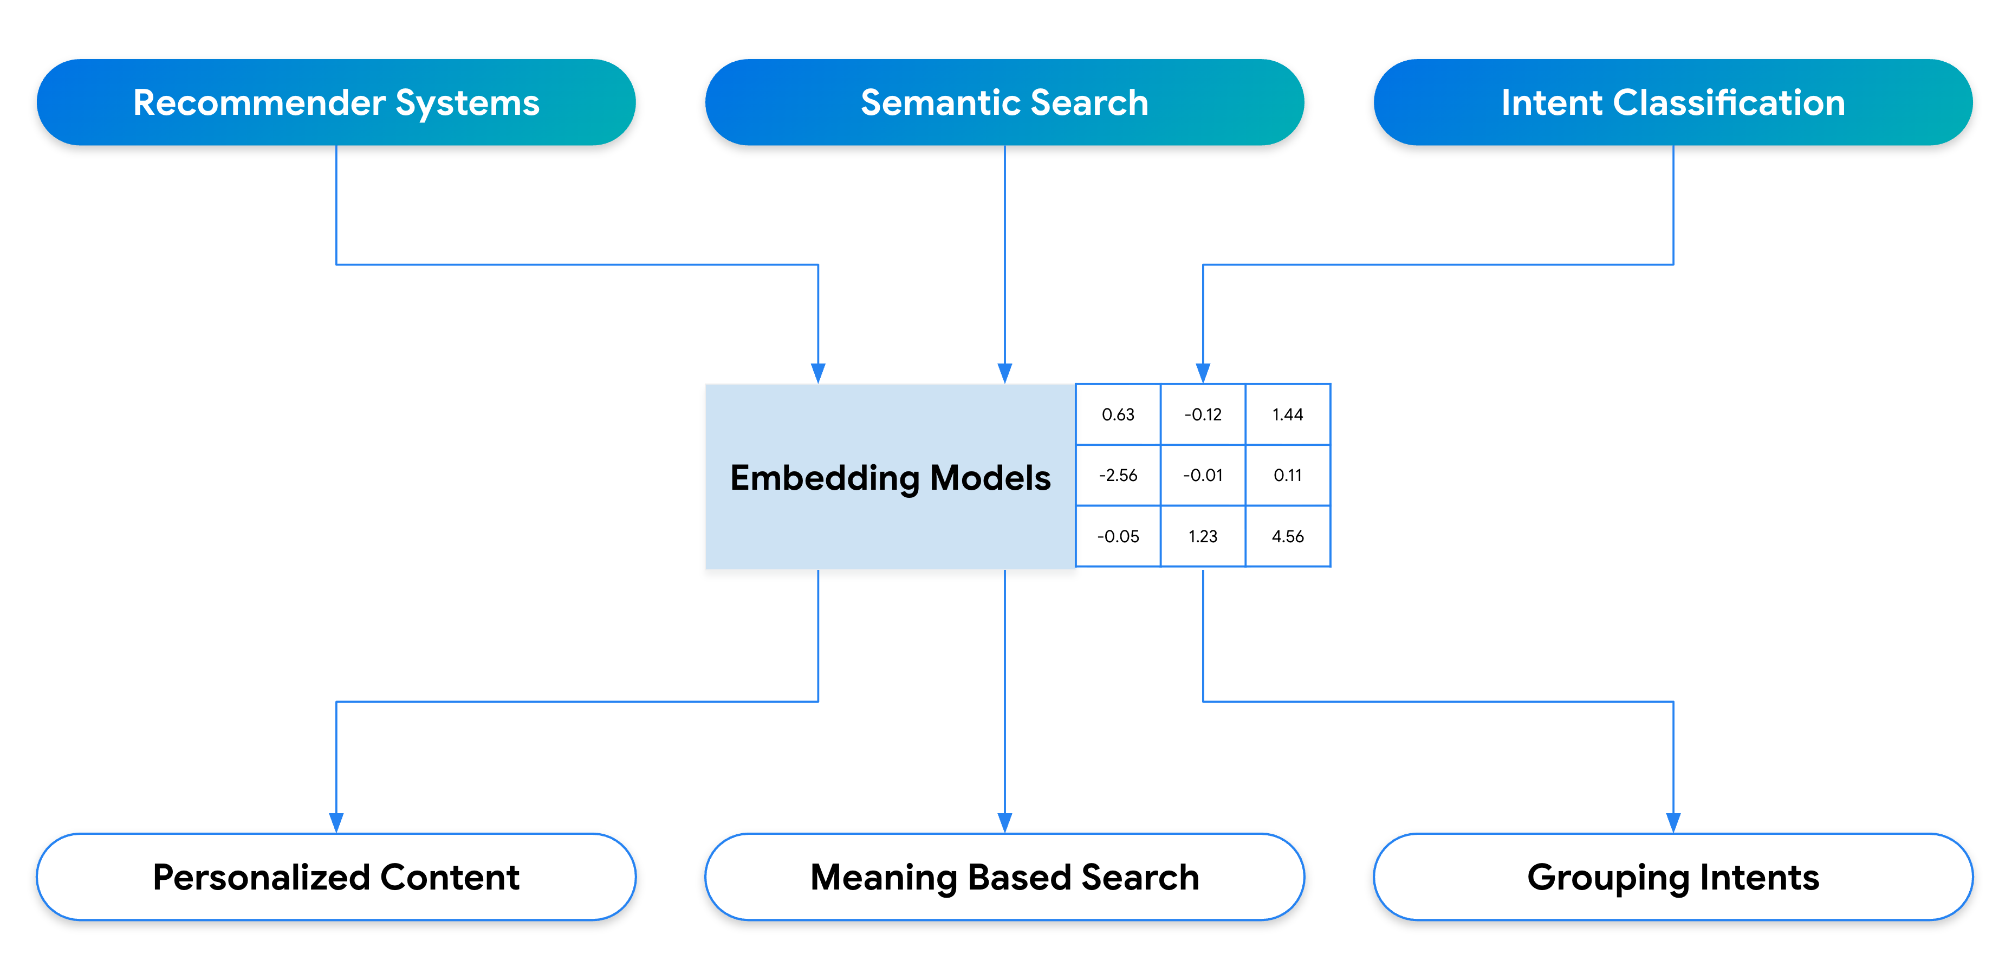
Figure 1. Embedding models enterprise capabilities.
To understand how embedding models work in practice, consider a standard vector search query. When a user queries a semantic search engine for the word “cat”, the model maps the token into a dense coordinate space. In this vector space, the mathematical distance between “cat” and “feline” or “dog” is short, yielding high similarity scores; conversely, terms like “hat” or “car” map to distant coordinates despite their orthographic similarity.
Seamless Elasticity with vLLM-TPU & GKE
While deploying small text embedding models for prototype applications is straightforward, scaling pipelines to serve millions of queries introduces different types of production bottlenecks. The most common ones we see are accessing elastic capacity of accelerators to seamlessly scale compute resources alongside dynamic traffic fluctuations and improving cost/performance efficiency.
To overcome these scaling and capacity constraints, Google Cloud has integrated native TPU support into vLLM — the industry-standard, highly optimized and popular open-source LLM serving engine. Standardizing on vLLM for TPU serving provides architecture true elasticity. Engineering teams can scale serving capacity up and down dynamically by provisioning TPU nodes directly alongside other XPU instances.
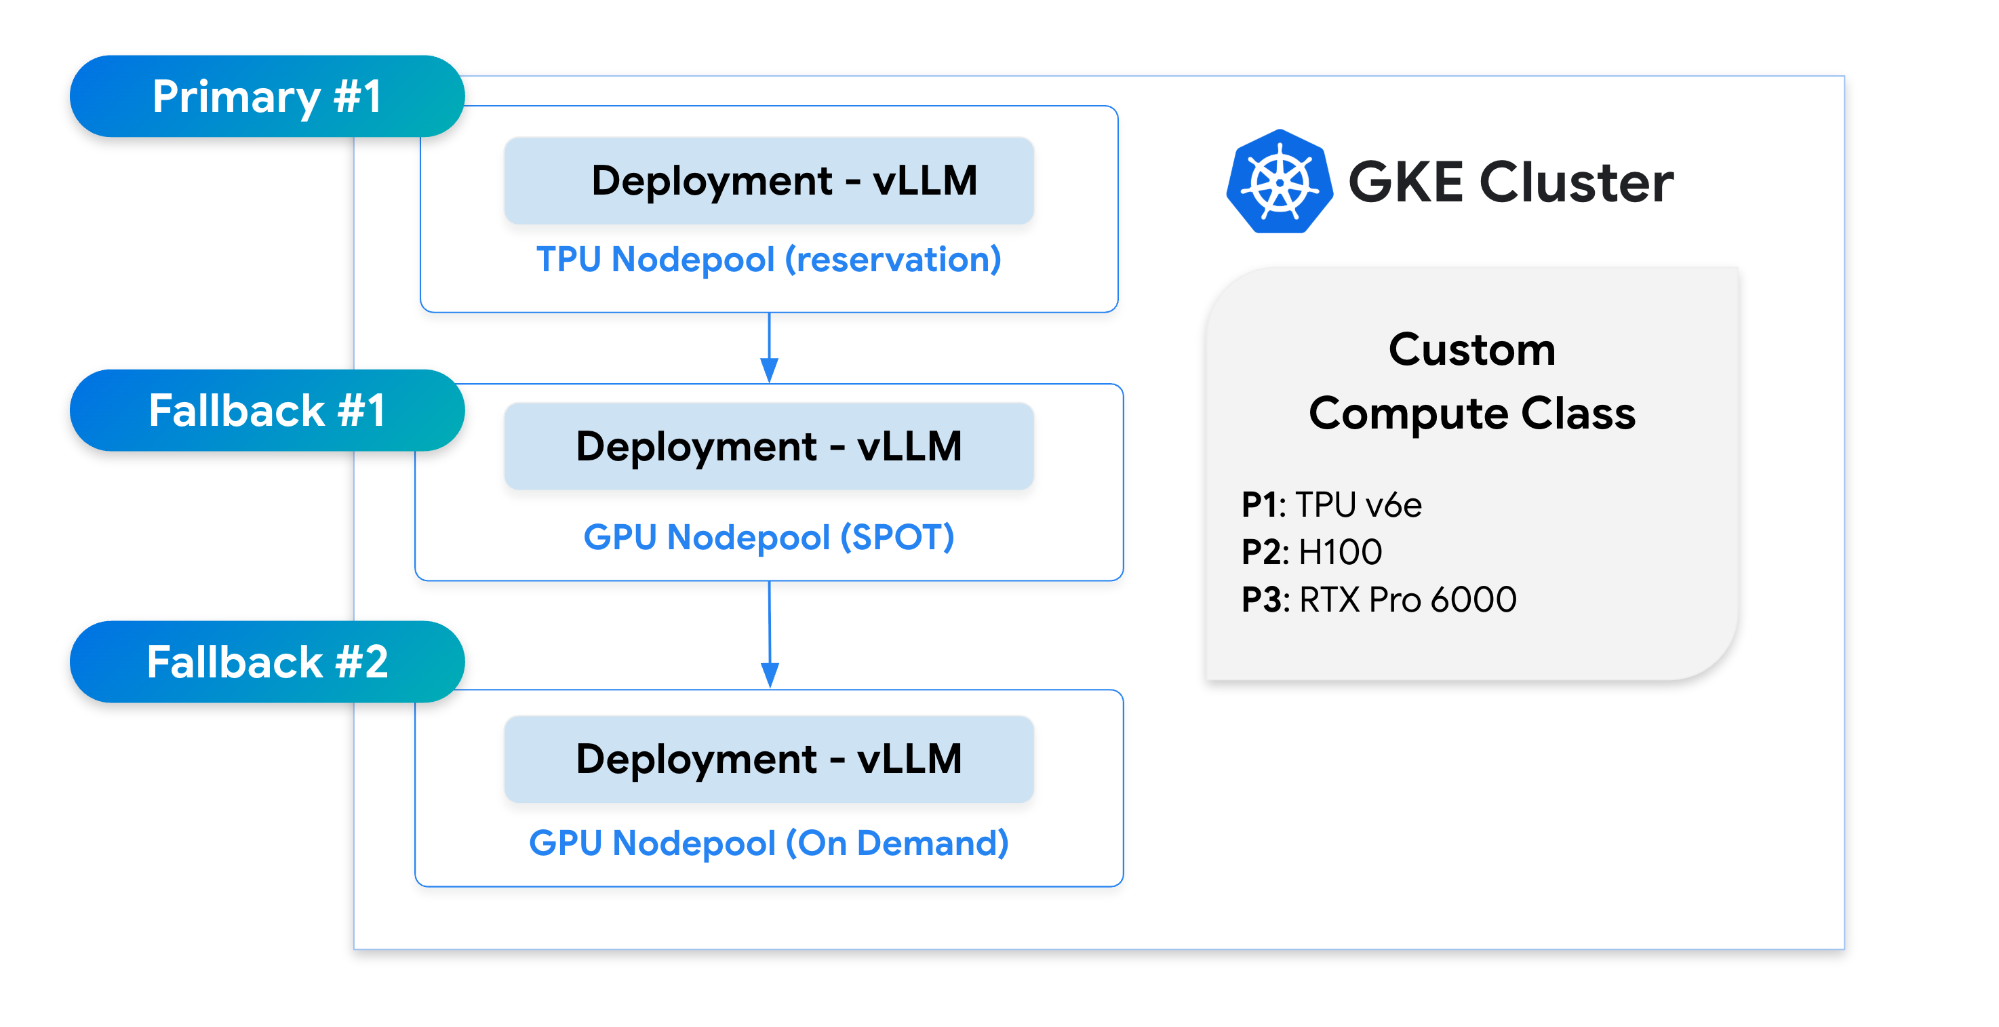
Figure 2. If primary TPU reservations are fully utilized, the serving infrastructure automatically falls back to secondary GPU spot or on-demand pools without interrupting incoming inference traffic.
By taking advantage of primitives like Custom Compute Classes in Google Kubernetes Engine (GKE), organizations can automate node autoscaling based on strict priority rules to scale up across different capacity types or accelerators if the previous one isn’t available.
Engineering High-Precision Embedding Support on TPUs
Serving next-generation embedding models in production demands processing ultra-long sequence contexts – ranging from 4K+ tokens for text workloads up to 15K+ tokens for multimodal text-and-image inputs. Crucially, enterprise applications require that these embeddings maintain strict mathematical parity and high precision across heterogeneous hardware backends compared to reference.
To bring high-dimensional vector pooling models to TPU hardware topologies, we took the Qwen3 Embedding model series as the target engineering models and engineered several key optimizations of the vLLM framework on TPU.
Challenge A: Hardware-Safe Tensor Alignment
TPU Matrix Execution Units (MXUs) impose strict divisibility constraints when sharding vocabulary matrices across topology meshes via Tensor Parallelism (TP). We implemented a unified, hardware-safe vocabulary padding strategy that guarantees exact tensor alignment during All-Gather execution.
Challenge B: Materialization Hardening, TPU Lazy-Loading & Compilation Pre-warming
vLLM relies on lazy-loading mechanisms on TPUs to minimize server cold-start latencies and reduce host memory peaks. To eliminate model initialization failures during lazy tensor transformations, we introduced attribute promotion within the unquantization pipeline, making weight loading fully compatible with vLLM’s TPU lazy-loader for zero-failure initialization.
Furthermore, to eliminate runtime JIT compilation latencies and avoid compilation traps in multi-processes deployments, we implemented sharding-aware pre-warming to lock JAX/XLA compilation caches prior to inference and stabilize the production pipelines and rollouts.
Challenge C: Long-Context StepPool Architecture
Ultra-long contexts require Chunked Prefill in the pooling layer to prevent High Bandwidth Memory (HBM) exhaustion, creating risk of state loss across step boundaries. We engineered a hybrid StepPool and migrated metadata to CachedRequestState, ensuring pooling states correctly accumulate across steps and survive request preemptions.
vLLM Embedding Sample on TPU
Below is a minimal example demonstrating how to initialize Qwen3-Embedding-8B on TPU. For complete setup scripts and environment deployment steps, refer to the official AI-Hypercomputer Qwen3-Embedding-8B Recipes on GitHub:
from vllm import LLM

# Initialize Qwen3-Embedding-8B on Cloud TPU using vLLM's native pooling runner
llm = LLM(
    model="Qwen/Qwen3-Embedding-8B",
    runner="pooling",             # Enables dense pooling output
    tensor_parallel_size=2,       # Sharded across TPU topology mesh
    max_model_len=16384,
    max_num_batched_tokens=512,
    dtype="bfloat16",
    trust_remote_code=True
)

# Extract dense vector embeddings across inputs
prompts = ["Enterprise-grade semantic retrieval on TPUs with vLLM."]
results = llm.embed(prompts)
embedding_vector = results[0].outputs.embedding
Python
Golden-Reference Precision & Numerical Parity
To certify enterprise-grade precision, we conducted rigorous mathematical parity evaluations comparing TPU outputs against other XPU golden references across multi-language and multimodal datasets.
To evaluate numerical alignment between dense embedding vectors generated on TPUs (vTpu) and reference baseline vectors generated on XPUs (vRef), we calculate their cosine similarity:
A cosine similarity score approaching 1.0 (with a target quality pass threshold of ≥0.999 for text and ≥0.995 for multimodal inputs) demonstrates near-perfect numerical parity across hardware backends. This confirms that optimizations implemented on the vLLM-TPU stack maintain golden-reference precision without sacrificing accuracy.
For step-by-step instructions on generating pairwise calculations, check out the official AI-Hypercomputer Qwen3-Embedding-8B Recipes on GitHub.
Qwen3-Embedding-8B (7K+ Tokens, TPU vs. CPU Baseline)
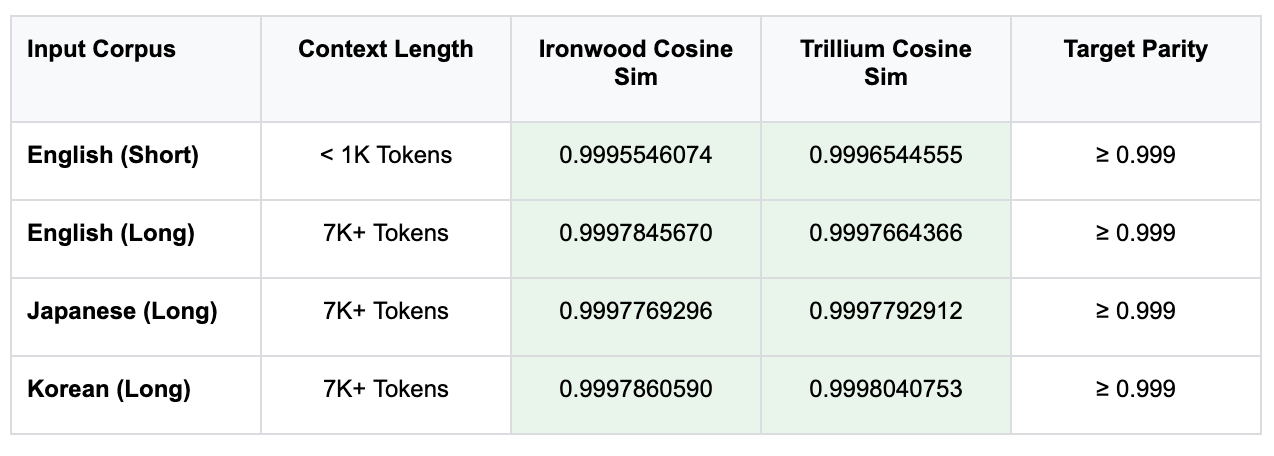
Table1. While maintaining strict numerical alignment, serving qwen-3-embedding-8b (bf16, 16K+ sequence length, TP=4) on TPU Ironwood achieved an impressive throughput of 83,996 total token/s and 5.13 req/s.
Qwen3-VL-Embedding-8B (15K+ Tokens, TPU vs. XPU Baseline)
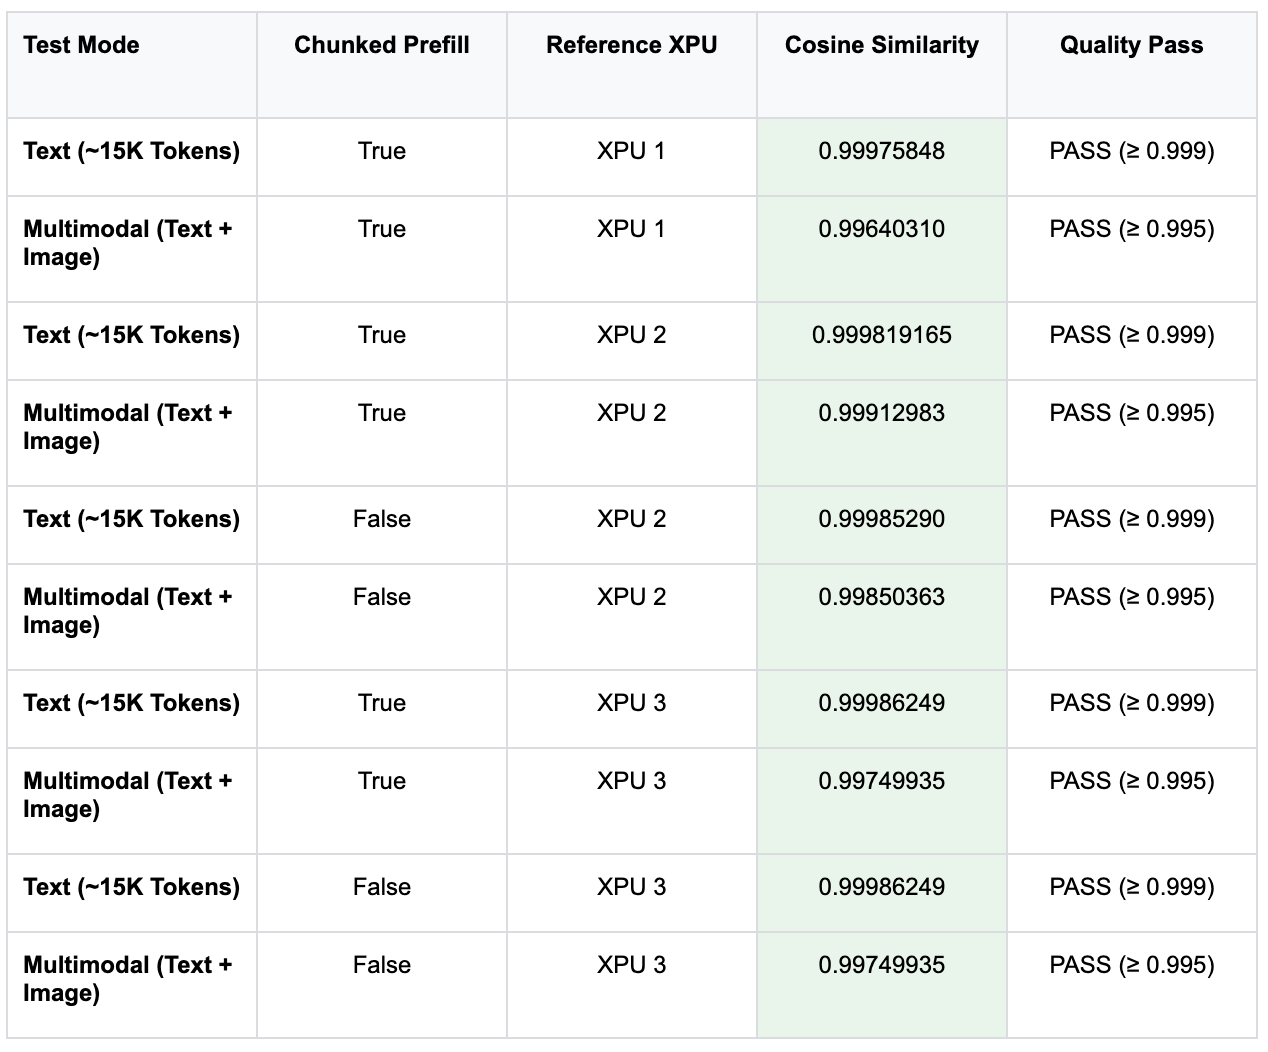
Table2. vLLM-TPU only chunks the text portion of multimodal prefill.
Public Recipes & Explore Resources
To help developers reproduce our numerical parity evaluations and rapidly deploy embedding workloads on Google Cloud TPUs, we have open-sourced official setup and execution recipes on the AI-Hypercomputer Public Repository.
Get Started:
* Qwen3-Embedding-8B TPU Recipe: Explore text embedding recipes at AI-Hypercomputer/Qwen3-Embedding-8B
* Qwen3-VL-Embedding-8B TPU Recipe: Explore multimodal embedding recipes at AI-Hypercomputer/Qwen3-VL-Embedding-8B
* vLLM TPU Engine: Explore more on vLLM framework on TPU at vllm-project/tpu-inference
* Google Cloud TPU Portal: Provision Cloud TPU instances and explore hardware specs at cloud.google.com/tpu
Acknowledgments
The engineering achievements and cross-hardware optimizations highlighted in this post were made possible through the incredible collaboration across Google Cloud Product, Engineering and the vLLM community.
[ad_2]
Source_link