[ad_1]
Most teams treat ‘which model’ as the important decision. The harness engineering literature keeps pointing somewhere else. In LangChain’s Terminal-Bench experiment, changing only the harness—same model throughout—moved a coding agent from roughly 30th place into the top 5.
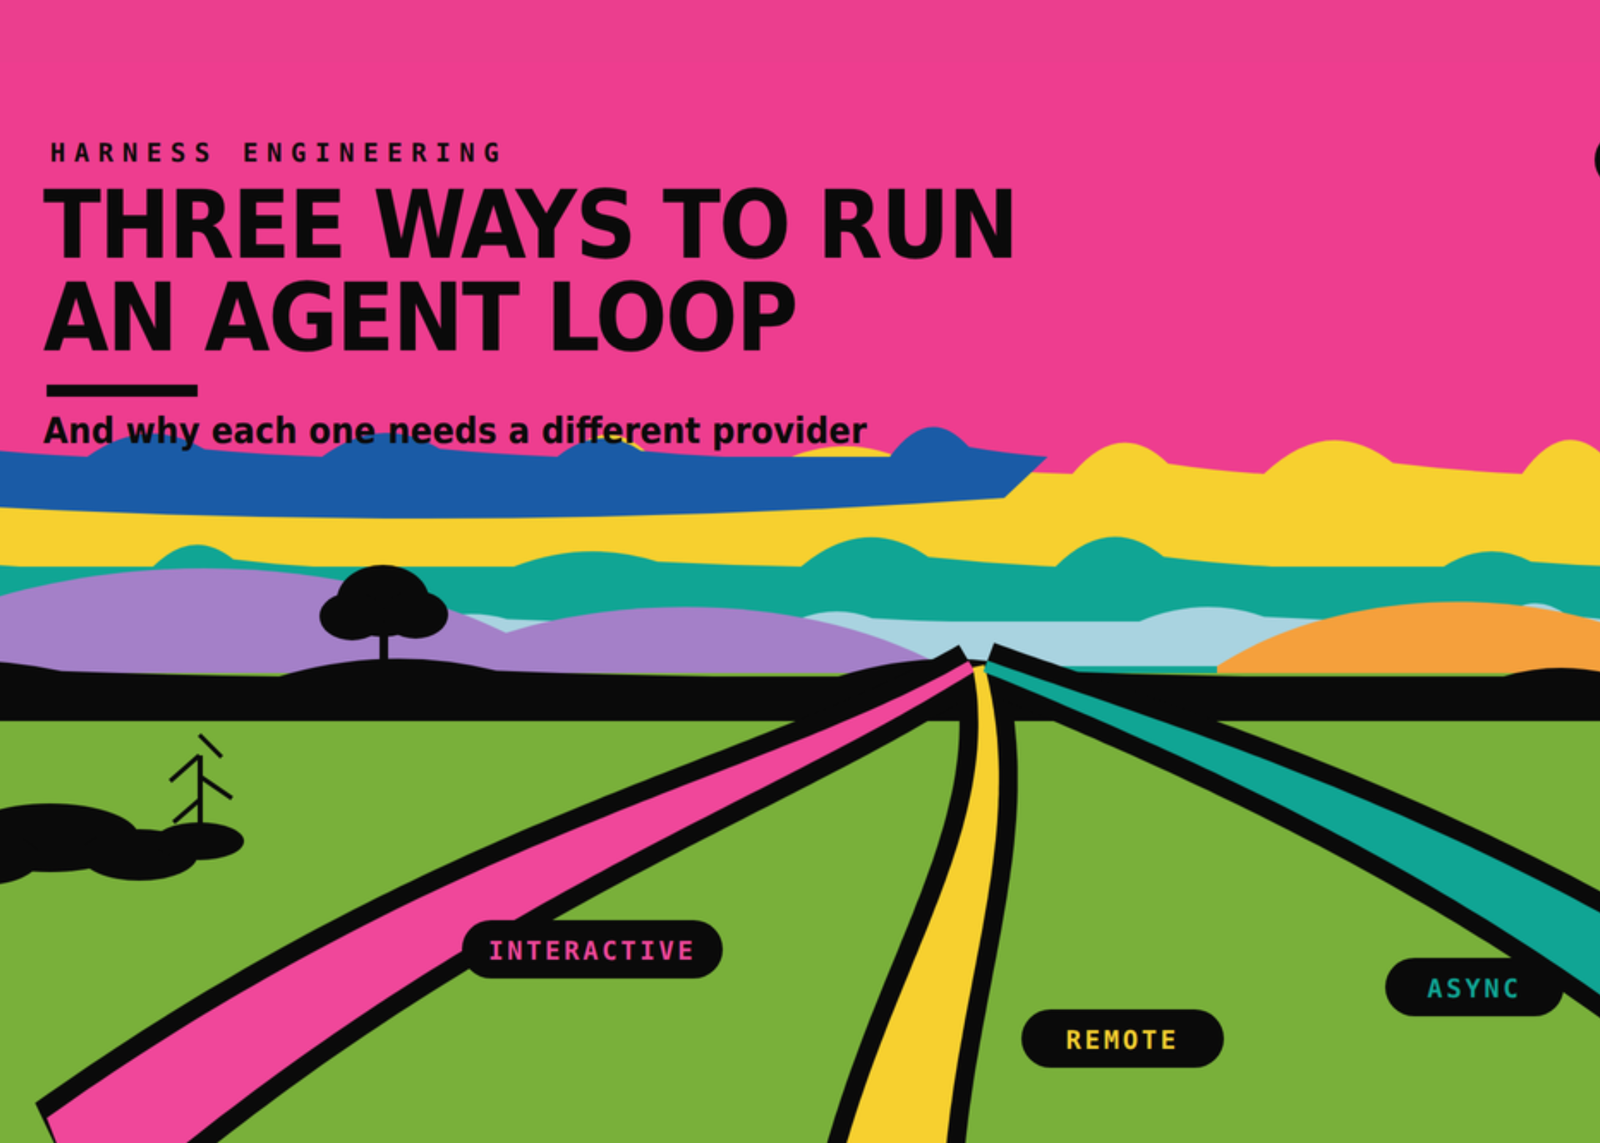
That result reframes the question. If the harness decides quality, then how you run the loop becomes an architecture decision, not a deployment detail. Paul Iusztin’s open-source course Building a Coding Agent From Scratch builds a Python agent called Decode. Published through Decoding AI, it separates three run modes. Each mode has a different latency profile. Each one therefore wants a different inference provider.
One headless core, three shapes
The center of the system is a headless harness with no interface of its own. Inside it runs the agent loop every harness shares: the LLM picks an action, a tool executes, the observation feeds back. Everything reads from and writes to the context window.
The agent itself is small. In Decode it is a ~20-line Pydantic AI definition composing a model, tools, and an output type. In Claude Code’s leaked source, the core loop is roughly 150 lines. Everything else—memory, skills, sandbox, permissions, LSP feedback, compaction—is harness.
Interfaces then plug into that core. That is where the three modes appear:
Mode 1: Interactive, online
A terminal UI is wired to one live session, in memory, in the same process. Events stream back through async generators as tokens arrive.
The hard problem here is steering. If you type while a tool call is in flight, injecting the message immediately corrupts the turn. Decode’s answer is a steering queue plus a priority gate. Input is buffered on arrival and injected only at a safe boundary. The loop exposes two: MODEL_REQUEST, before the next model call, and WOULD_STOP, when the turn would end.
Three input modes map onto that. Plain Enter steers within the turn. Alt+Enter queues a follow-up until the turn stops. Esc triggers a cooperative abort at the next boundary, clearing both queues so history stays intact.
A human is reading every token. This mode is latency-bound, which is why it belongs on a low-latency hosted API.
Mode 2: Remote, offline
Remote mode keeps the harness headless and runs it on a server through an agent runtime. Decode uses Kitaru, ZenML’s agent runtime, deployed to GCP, with the agents themselves executing on Modal.
Nobody is watching. A backlog of tickets fans out to N harnesses in parallel, each producing its own PR. Because the runtime records progress step by step, a sandbox that dies mid-task resumes from its last recorded step instead of restarting. A run that pauses for human input freezes and consumes no compute while it waits.
Tools execute inside Modal Sandboxes remotely, Docker locally. The metric that matters is throughput per dollar, not time-to-first-token.
Mode 3: Async, online
The third shape sits between the two. A live session hands work to a job queue and returns immediately. Background workflows fan out LLM calls and post results back later.
The user is online but not watching each step. The queue owns the work, so the run outlives the client that started it. This is the pattern behind Slack-triggered agents and background PR review, and it bills like batch, not like chat.
The interactive explainer
Why the provider changes with the mode
The cost model follows the latency requirement, and the gap is large.
Take 1,000 documents at 30,000 input tokens each, roughly 500 output tokens per document. At frontier API rates of $3 per million input and $15 per million output, the lesson’s arithmetic lands near $97. Prompt caching does not rescue it, because every document is a different prefix. Batched on a serverless GPU at around 3,000 tokens per second, the same work is under three hours of GPU time—roughly $13.
The reverse case is just as sharp. Decode’s default test model, Qwen3.6 35B, runs on a single H200. Modal’s published pricing lists H200 SXM at $0.001261 per second, or about $4.54 per hour. Leave an interactive agent idle overnight waiting on a y confirmation, and ten idle hours add roughly $45 to the bill.
That is the whole argument. Interactive work pays per token because a human is waiting. Offline and async work pays per GPU-hour because throughput is the objective and idle time is the enemy.
There is a second axis: serverless versus reserved capacity. Modal’s pricing analysis reduces it to one comparison. Reservations charge the peak rate for the whole contract; serverless follows the demand curve. When the peak-to-average ratio exceeds the reservation discount, serverless is cheaper. Modal reports typical discounts of 2–5× against peak-to-average ratios of 5–10× for inference, training, and agentic development. Industry surveys it cites put reservation utilization below 30%, often under 10%.
Key Takeaways
- Harness beats model: swapping only the harness moved an agent from ~30th to top 5 on Terminal-Bench.
- Interactive mode is latency-bound and steers via a queue draining at
MODEL_REQUESTandWOULD_STOPboundaries. - Remote and async modes are throughput-bound, so GPU-hour billing beats per-token billing at volume.
- 1,000 documents cost ~$97 on frontier API rates versus ~$13 of batched GPU time.
- Serverless wins whenever peak-to-average demand exceeds the reservation discount, typically 5–10× against 2–5×.
Sources:

Michal Sutter is a data science professional with a Master of Science in Data Science from the University of Padova. With a solid foundation in statistical analysis, machine learning, and data engineering, Michal excels at transforming complex datasets into actionable insights.
[ad_2]
Source_link